
Global Industry Brief: Edge AI Development Stacks Are Being Rebuilt Around the Toolchain, Not the Model
AI & Data News · industry desk · By David Nakamura
Model accuracy is rarely the reason an edge AI program misses its date. The schedule pressure usually sits one layer lower, in the repetitive work required to land a trained model on embedded hardware — and that is precisely where the component industry has been restructuring its development stacks. Across recent product cycles, NXP, TI, Renesas, Microchip and Altera Corp. have each made moves aimed at the same friction from different directions: a cloud-based AI hub, a consolidated toolchain ecosystem, a platform that pulls board design into the software workspace, compilers taken off a paywall, and a spatial compiler for FPGA accelerators. Read side by side, those announcements describe a shift from individual tools toward complete ecosystems.
At a glance: the dates and numbers behind the shift
- 2018 — NXP Semiconductor launched the eIQ software development platform, which has since evolved away from a code-heavy inference engine compiler into the GUI-based eIQ toolkit.
- CES 2026 — NXP launched the eIQ AI hub, bringing the eIQ toolkit, eIQ Time Series Studio, eIQ GenAI Flow and a new agentic AI framework onto one cloud-based platform.
- over 200 — pretrained, hardware-optimized neural-network models in TI's Model Zoo, based on PyTorch, TensorFlow and ONNX and covering vision, audio, time-series and radar use cases.
- January 2026 — the C7 NPU launch that pairs with the TDA5 SoC for cross-domain fusion in automotive systems.
- June 2026 — Renesas acquired Pictorus, whose Rust-based code generator is slated for integration into Renesas 365.
- Licensing — MPLAB XC Pro Compilers and the MPLAB ML Development Suite are now free of charge, with unlimited installations for individuals and development teams.
- FPGAs — Altera added spatial mapping tools to its FPGA AI Suite, while Microchip continues to enable model deployment on PolarFire devices via VectorBlox SDK.
The porting loop, not the model, is where engineering time disappears
When larger AI and machine-learning (ML) models must run at the edge, embedded development becomes more complex, slower and costlier. Because embedded edge devices vary in architecture, a model generally needs conversion, quantization or other optimization, compilation for the target runtime, and then empirical benchmarking and validation on the target hardware. Repeating that workflow across many hardware platforms consumes time and has become a critical bottleneck for development teams, while framework incompatibility across different silicon vendors complicates the job further.
Against that backdrop, each vendor's platform work targets the same four objectives: accelerating model optimization, handling heterogeneous hardware, strengthening security hardening — crucial for mission-critical applications under real-time performance constraints — and lowering the cost of entry for developers. The figure below maps the bottleneck pattern the industry is trying to dissolve.
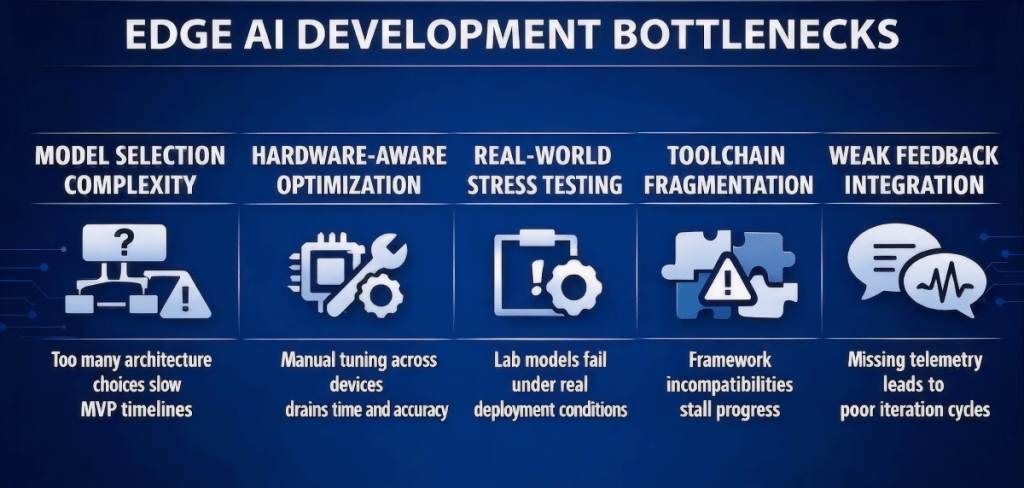
Figure 1: Edge AI development bottlenecks (Source: Saumitra Jagdale)
NXP: an inference toolkit matures into a hosted hub
The GUI-based eIQ toolkit works in a single, unified workflow: it performs graph-level profiling first and then optimizes open-source TensorFlow, PyTorch and ONNX models, with quantization, operator fusion, pruning and architectural mapping supporting model optimization. Extensions integrated with the Nvidia TAO toolkit let models be imported from that environment.
Time-series work sits in eIQ Time Series Studio, a platform for time-series AI/ML development that is crucial for real-time decision-making at the edge. It is tailored for NXP's i.MX 8 and i.MX 9 application processors, QorIQ Layerscape processors such as LS1046A, LX219 and 760A, and S32 automotive processors and microcontrollers (MCUs).
The step change came at CES 2026, when the company introduced the eIQ AI hub: the eIQ toolkit, eIQ Time Series Studio, eIQ GenAI Flow — a software pipeline for large language models — and an agentic AI framework all gathered on a unified, cloud-based platform. Functional simulations, hardware farming of models and benchmarking tests run there, and teams keep the flexibility to switch development from the cloud to on-premises if required. Effectively, NXP is applying to agentic AI at the edge the same acceleration logic it previously applied to the rest of the eIQ tool suite.
That framework is also compatible with NXP's Ara discrete neural processing units (NPUs). Because multi-model workflows in constrained edge environments necessitate heterogeneous computing, inference workloads are distributed intelligently across Ara NPUs, i.MX CPU cores and integrated GPU acceleration.
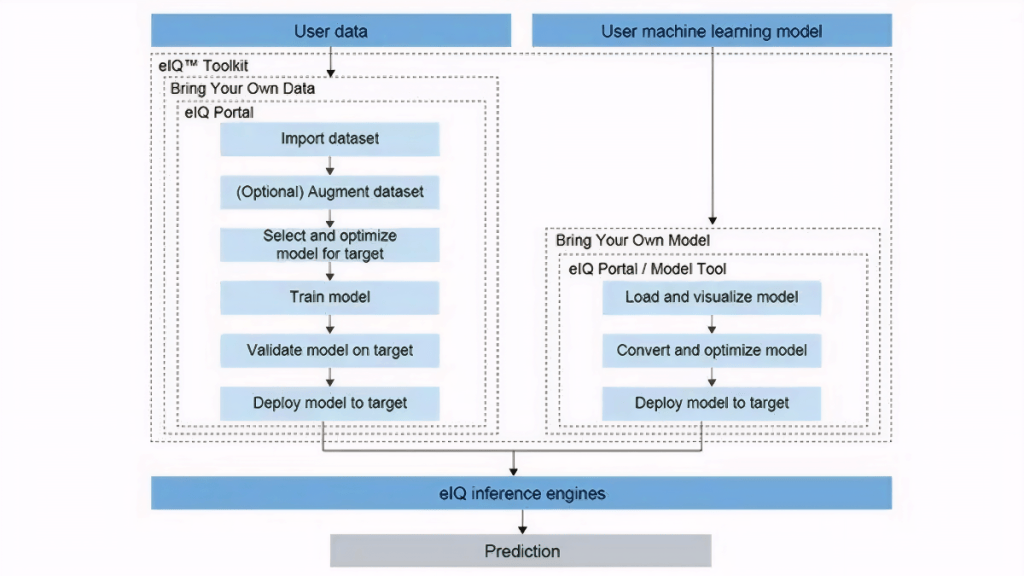
Figure 2: NXP's eIQ Toolkit ML development pipeline (Source: NXP Semiconductors)
TI: consolidate the toolchain, then open the model shelf
The CCStudio development ecosystem from Texas Instruments Inc. is organized around consolidation. TI says it unites disparate hardware architectures, graphical configuration tools, compilers and edge AI deployment into one cohesive workflow, with tools for data collection, training, optimization and deployment of models provided across a portfolio spanning the MSPM0, C2000, MSP430, SimpleLink, Hercules, Sitara, Jacinto, mmWave, C6000 and C7x families.
The resource library is the second half of the offer. Model Zoo contains over 200 pretrained and hardware-optimized neural-network models based on the PyTorch, TensorFlow and ONNX frameworks for vision, audio, time-series and radar use cases, and these model deployments are heavily based on advanced data signaling. Remote benchmarking closes the loop: as with NXP's AI hub, developers can benchmark neural networks on TI hardware over the cloud via Model Analyzer, while CCStudio also empowers developers with AI agents that accelerate code generation, system configuration and debugging.
Automotive shows how far the toolchain story extends. TI collaborated with Synopsys to develop a Virtualizer Development Kit for digital twinning of the TA5 system-on-chip (SoC), creating software-defined hardware for automotive applications. Integrated with the C7 NPU launched in January 2026, the TDA5 SoC enables enhanced cross-domain fusion in advanced driver-assistance systems, gateway control and infotainment hosting — all on one device.
Renesas 365: board design joins the embedded software workspace
Renesas Electronics Corp. assembles a broader set of tools, accelerating the development workflow not only at the software level. Chiefly, Renesas 365 brings Altium Designer and e2 studio, the company's integrated development environment, under the same umbrella, allowing higher-level hardware-software co-design.
Because the platform is structured to hold all the tools at a single stop — the System Data Model — Renesas 365, equipped with an integrated suite of AI-driven tools, can unify board-level hardware design, system-level simulation, component sourcing and embedded software compilation into one cohesive ecosystem.
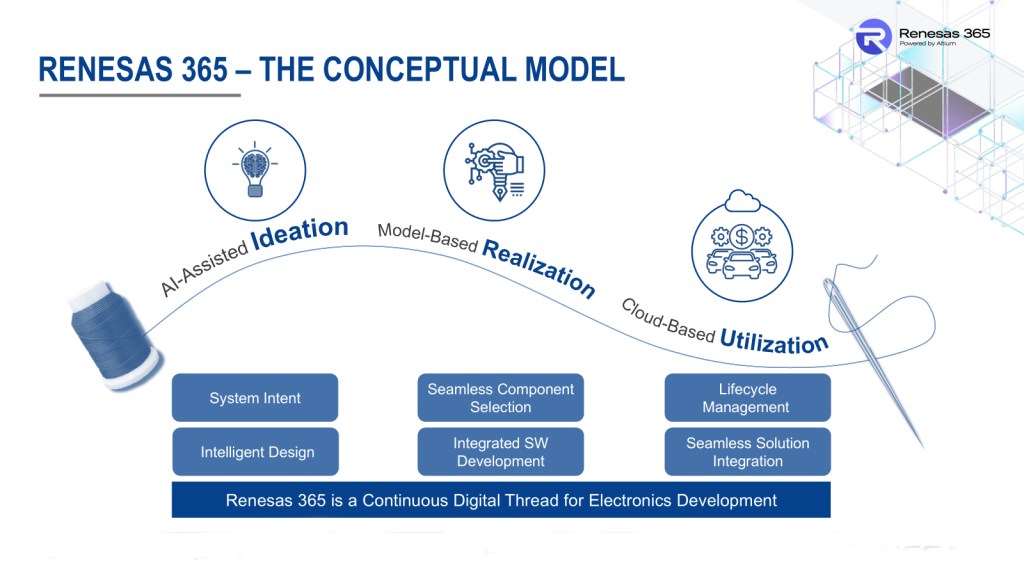
Figure 3: How the Renesas 365 platform is structured to fill gaps in the embedded systems development workflow (Source: Renesas Electronics Corp.)
Model work is handled inside the same boundary. To streamline model training, optimization and deployment, Renesas integrated its Reality AI tools into the cloud-based Renesas 365 platform, as shown in Figure 4: the tool analyzes sensor data to create a tailored model, then streamlines training and optimization within a single, end-to-end workflow.
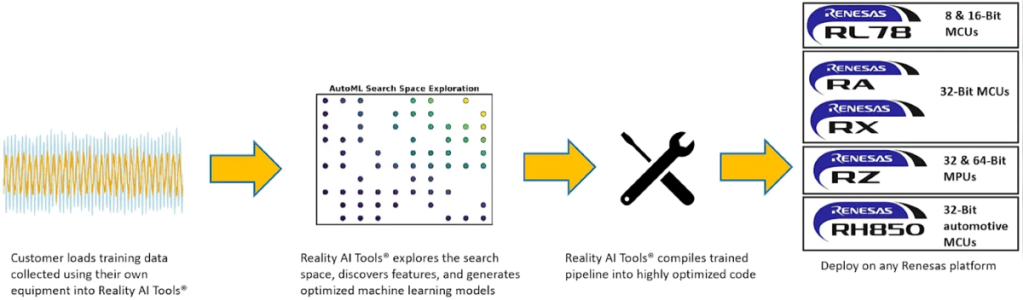
Figure 4: How Renesas's Reality AI tool accelerates model deployment (Source: Renesas Electronics Corp.)
The next acceleration depends on an acquisition still being absorbed. Renesas acquired Pictorus in June 2026; once its Rust-based code generator for behavioral modeling is assimilated into Renesas 365, it is intended to expedite validating algorithms, running virtual prototypes and deploying edge applications.
Microchip: take the licence fee out of the compiler path
Microchip Technology Inc. offers an Edge AI Development Suite that supports its MCU and microprocessor (MPU) portfolio by integrating silicon, software and development tools for edge AI and IoT applications. The change drawing attention is commercial rather than technical: the MPLAB XC Pro Compilers and the MPLAB ML Development Suite are now available free of charge.
By removing licensing barriers for developers, code optimization features such as code size reductions and boosting code execution — features of the MPLAB XC PRO Compiler — are no longer hidden behind an expensive paywall. The updated licensing model allows unlimited installations for both individual users and development teams, providing unrestricted access to compiler optimization features and ML development tools across the company's MCU and MPU platforms.
On the deployment side, the MPLAB ML Development Suite is a comprehensive tool for products such as the dsPIC33 family, PIC32 MCUs and SAM MPUs. Its centerpiece is Model Builder, a Microsoft VS Code extension that automatically generates code based on raw sensory data — and Microchip also dropped licensing costs from this plug-in.
FPGA inference is still a structurally harder target
The stacks described so far support edge AI deployment mainly on MCUs, SoCs, NPUs and GPUs — that is, fixed-function silicon. Deploying models on FPGAs remains more nuanced and complex. Where fixed-function inference relies largely on software, AI inference on FPGAs requires software-hardware co-design: the hardware-accelerator matrix must be explicitly configured to match the memory layout, data types and layer operations defined by the compiled neural-network model.
To bypass tedious low-level hardware configuration, silicon vendors have conventionally opted to configure a fixed processing architecture and run ML models on an abstract layer via an overlaying architecture. Given FPGA resource constraints, developers have typically chosen to map models into multiple layers and run them on the overlay sequentially — and that sequential mapping creates a critical latency bottleneck in real-time edge applications.
Pure-play FPGA provider Altera Corp. responds with its FPGA AI Suite, a solution for creating AI accelerators on its FPGAs and SoCs that has supported design through sequential mapping; the company recently introduced spatial mapping tools in the toolchain suite. Supporting Altera Agilex 5, Agilex 7, Arria 10, Cyclone 10 GX and Stratix 10 FPGAs, the suite now has a spatial compiler that generates dedicated RTL using blocks from a pre-optimized library. Because development becomes more application-specific, it enables deterministic, higher-throughput performance for real-time computer vision, video analytics, natural language processing and sensor fusion tasks, and it also shortens development time.
FPGA deployment is not exclusive to that supplier: Microchip also enables model deployment on its PolarFire FPGAs, where developers can deploy TensorFlow, TensorFlow Lite, ONNX and OpenVINO-based models via the VectorBlox SDK.
Side by side: what each rebuilt stack targets
| Vendor / platform | Structural change | Barrier it addresses |
|---|---|---|
| NXP — eIQ AI hub | Toolkit, Time Series Studio, GenAI Flow and agentic AI framework on one cloud-based platform, extendable to on-premises | Fragmented tools; no shared simulation, hardware farming and benchmarking environment |
| TI — CCStudio | Toolchains, graphical configuration, compilers and edge AI deployment unified; Model Zoo plus Model Analyzer and AI agents | Reinventing training and benchmarking per architecture and per product family |
| Renesas 365 | Altium Designer and e2 studio under one umbrella over the System Data Model, with Reality AI in the cloud platform | Hardware design, simulation, sourcing and software compilation living in separate silos |
| Microchip — Edge AI Development Suite | MPLAB XC Pro Compilers and MPLAB ML Development Suite free; unlimited installations; Model Builder plug-in cost removed | Paywalled optimization; per-seat licensing for teams |
| Altera Corp. — FPGA AI Suite | Spatial mapping tools and a spatial compiler generating dedicated RTL from a pre-optimized library | Latency of sequential overlay mapping; manual accelerator configuration |
FAQ: what product and data teams are asking
Is the bottleneck really the toolchain rather than the model?
The stated workflow explains why. Model conversion, quantization or other optimization, compilation for the target runtime and empirical benchmarking on the target hardware must be repeated as devices vary in architecture, and repeating that workflow across many hardware platforms is time-consuming. Framework incompatibility across different silicon vendors compounds it, which is why vendors are rebuilding workflows instead of shipping another single tool.
Will the platforms accept models I already train?
Open-source framework support is the common denominator. The eIQ toolkit optimizes TensorFlow, PyTorch and ONNX models and can import from the Nvidia TAO toolkit; TI's Model Zoo models are based on PyTorch, TensorFlow and ONNX; Microchip's VectorBlox SDK on PolarFire covers TensorFlow, TensorFlow Lite, ONNX and OpenVINO-based models.
Does cloud adoption mean giving up local control?
Not in the designs described. The eIQ AI hub is a cloud-based platform but retains flexibility to switch development from the cloud to on-premises; TI's Model Analyzer benchmarks neural networks on TI hardware remotely over the cloud; Renesas 365 is likewise cloud-based, with its System Data Model acting as the single stop for tools.
What changed in real cost terms?
The clearest example is Microchip: the MPLAB XC Pro Compilers and MPLAB ML Development Suite are now free of charge, the code size reduction and execution-boost capabilities of the MPLAB XC PRO Compiler are no longer behind a paywall, and the updated licensing model allows unlimited installations for individuals and teams, including the Model Builder plug-in.
Why do FPGAs still need a separate workflow?
Because the accelerator's hardware matrix has to be configured to the compiled model's memory layout, data types and layer operations. Sequential mapping across overlay layers solves resource constraints but creates a latency bottleneck in real-time edge applications — the gap Altera's new spatial compiler, with dedicated RTL, is positioned to reduce.
Closing read: coverage of the workflow is becoming the competitive variable
The through-line across these announcements is that building development ecosystems has become essential in itself. Supporting open-source frameworks, eliminating licensing fees and running edge AI across a range of hardware platforms do more than collapse offerings into a single product: they promote multi-architecture compatibility, strengthen open-developer communities and advance cross-platform standardization.
Three follow-ups deserve attention. Whether Pictorus's Rust-based code generator is fully assimilated into Renesas 365 will determine how far hardware-software co-design actually compresses validation cycles. Whether spatial mapping narrows the latency penalty left by sequential overlays will decide if FPGAs can hold real-time edge workloads previously reserved for fixed-function silicon. And whether zero-cost compiler licensing spreads beyond Microchip's current offer will shape how small teams enter the market. For buyers and builders alike, the practical comparison is shifting from "which chip performs best" to "which stack removes the most repetition".